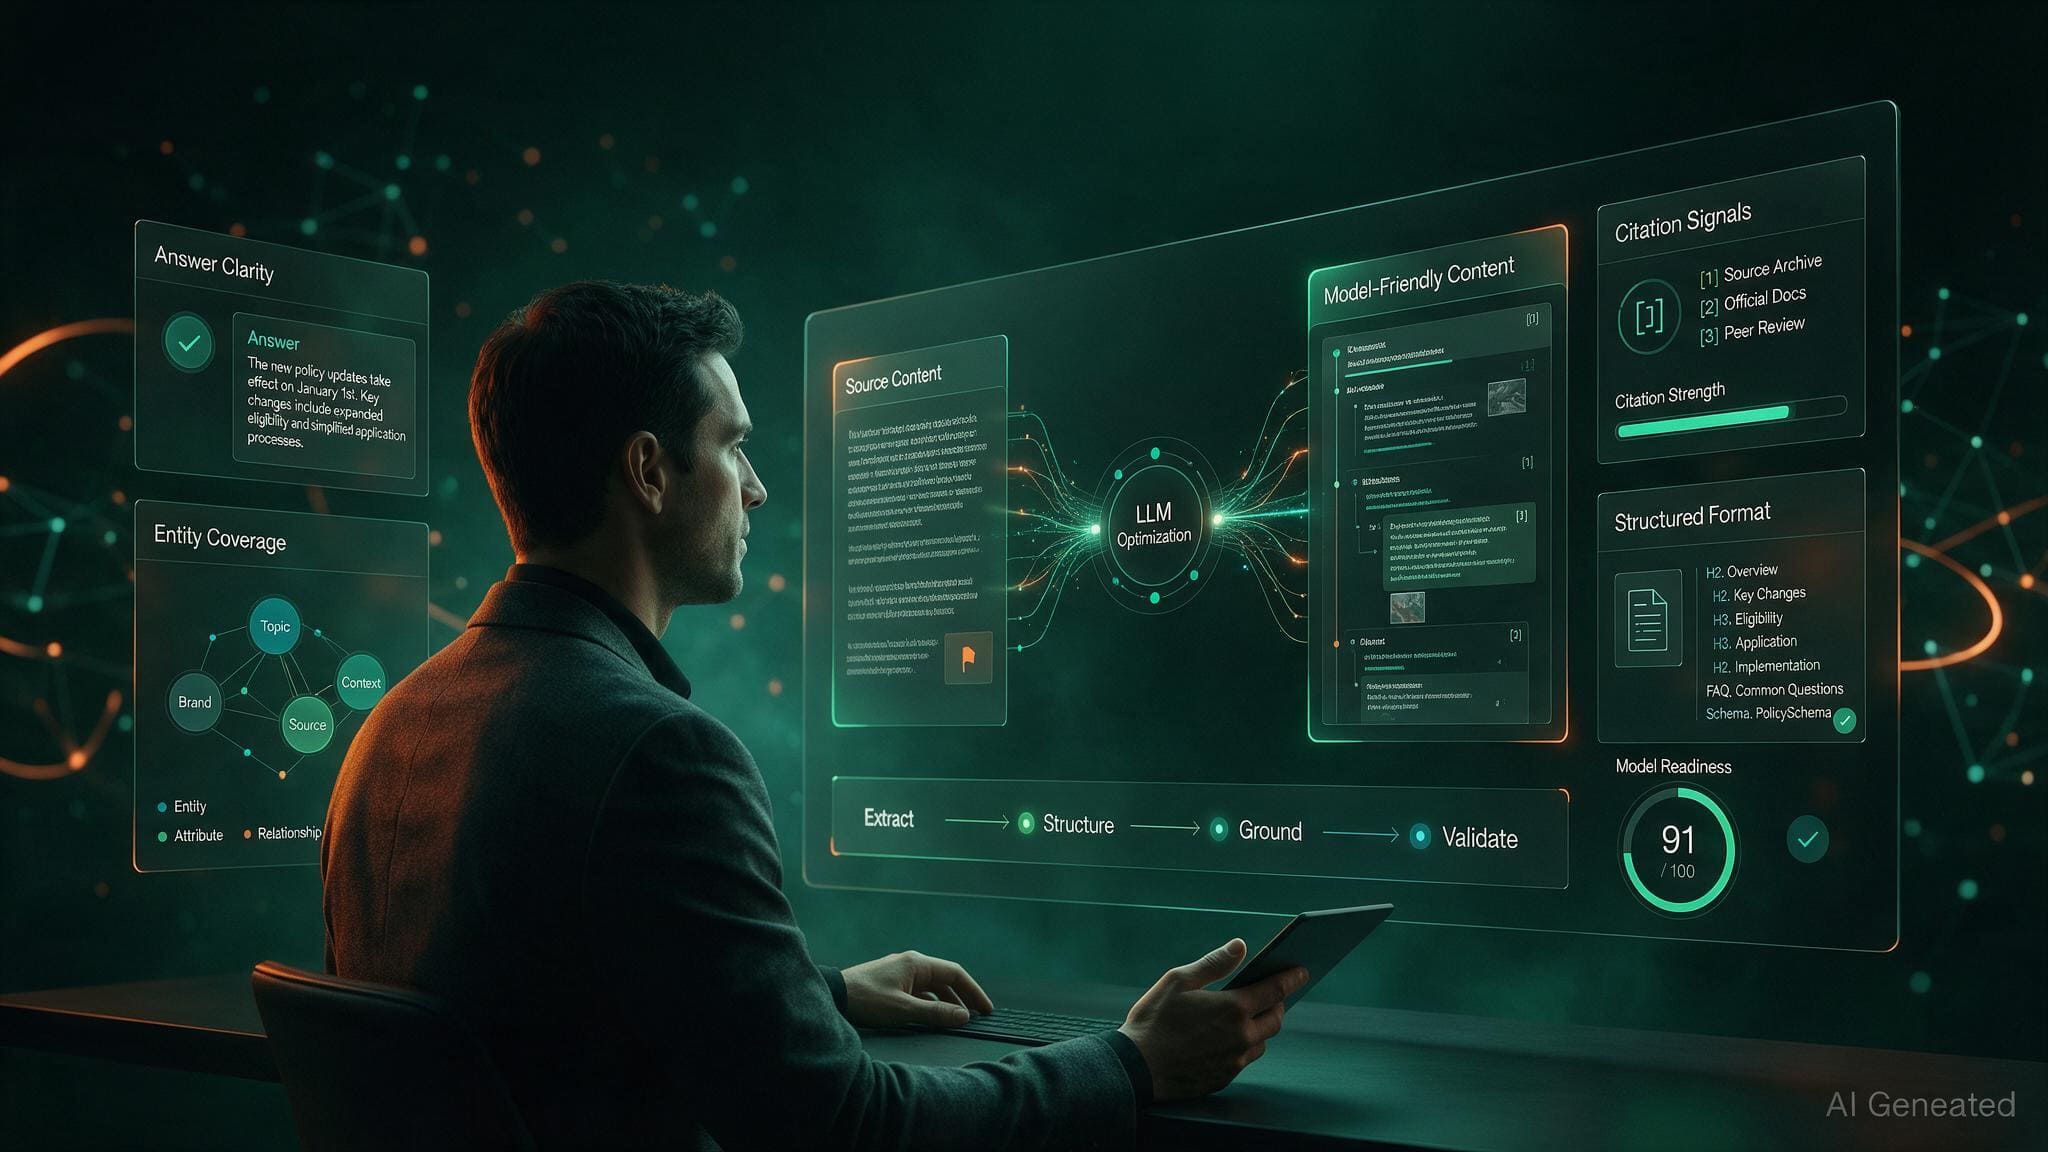
Quick answer: LLM optimization means writing paragraphs that a retrieval-augmented generation (RAG) system will actually surface for a real reader’s question — not just paragraphs that follow word-count and formatting rules of thumb. Retrieval is governed by meaning, measured as vector similarity, not by whether a paragraph happens to be the right length or avoids certain phrases. The only reliable way to know whether your content clears that bar is to test it against a real embedding model, using a tool like the free Real Retrieval Simulator, rather than assuming the rules of thumb are enough.
Most AI-content advice stops at formatting: keep paragraphs between 50 and 120 words, avoid phrases like “as mentioned above,” put one idea per paragraph. These rules exist for real reasons and are worth following — see the technical SEO foundations for AI-first search for the fuller picture. But following all of them doesn’t guarantee a specific paragraph will actually be retrieved for a specific question, because retrieval isn’t governed by word count or checklist compliance. It’s governed by meaning — how close a paragraph sits to a question in vector space, the same underlying math that determines what a RAG system pulls into an answer.
This is the step that comes after confirming your content covers the right entities. Entity coverage answers whether the right concepts are present at all. LLM optimization answers a narrower, later question: once the concepts are there, would a retrieval system actually find and quote the specific paragraph that covers them? A page can pass the first check and fail the second — and the two failures look completely different, which is why the citation economy rewards both information density and structural retrievability, not one or the other.
What Does “Model-Friendly” Actually Mean for a Piece of Content?
A retrieval-augmented generation system doesn’t read a whole page and reason about it the way a human does. It splits content into chunks — usually paragraph-sized — converts each chunk and the incoming question into vectors using an embedding model, and measures how close each chunk sits to the question in that vector space. The chunks that score highest get pulled into the AI’s answer. Model-friendly content is content written so that its chunks sit close to the questions a real reader would ask, not content that merely follows a style guide.
This is a genuinely different target than most AI-writing advice implies. A paragraph can be exactly 80 words, avoid every banned phrase, and cover one clean idea — and still score poorly against the question it was meant to answer, because its specific wording drifts from how that question is actually phrased. Conversely, a paragraph that technically breaks a formatting rule can retrieve well if its meaning sits close enough to the question. The rules of thumb are proxies for retrievability. They are not retrievability itself.
Why Doesn’t Following Word-Count and Formatting Rules Guarantee Retrieval?
Because none of those rules measure the thing that actually determines retrieval: semantic distance between a paragraph and a question. Two structurally identical paragraphs — same length, same one-idea-per-paragraph discipline, same absence of dangling references — can score very differently against the same question if one happens to use vocabulary closer to how the question is phrased.
Dangling references are the one formatting issue that reliably hurts retrieval regardless of wording, and they’re worth calling out specifically. A paragraph that opens with “This approach solves the problem by…” or “As mentioned above, the result was…” depends on context that isn’t present in the chunk itself once a retrieval system pulls it out in isolation. The paragraph might be well-written and topically on point, but if it doesn’t name its own subject, an isolated chunk reads as incomplete — which is exactly the condition it will be read in in retrieval.
How Do You Actually Test Whether Your Paragraphs Are Retrievable?
Guessing which paragraphs would retrieve well means either trusting the formatting rules blindly or manually imagining how an embedding model would score your text — neither is reliable. The only direct method is to run the actual measurement: embed your content and a set of realistic questions, then compute real similarity between them.
That’s what the free Real Retrieval Simulator does, entirely inside your browser. Paste your content, click “Suggest candidate questions” for a free keyword-based starting list (then edit it with the real questions your audience asks), and click “Simulate retrieval.” The tool chunks your content on natural paragraph boundaries, loads an open-source embedding model (all-MiniLM-L6-v2, downloaded once and cached by your browser), and computes actual cosine similarity between every paragraph and every question. The output is a heatmap, a Retrieval Coverage Score, a list of coverage gaps — questions nothing on the page answers well — and a list of weak chunks flagged for dangling references or awkward length.
Because the embedding step runs client-side, nothing you paste is sent to an AI provider, and results are reproducible: the same content and questions produce the same similarity scores every time, since it’s a mathematical measurement rather than a generated response.
How Should You Prioritize Fixes Once You See the Heatmap?
A heatmap full of mixed scores can be overwhelming to act on if you treat every weak cell as equally urgent. Work in this order instead:
- Close complete coverage gaps first. A question with no matching paragraph anywhere on the page is a fully missed angle — a bigger loss than a paragraph that’s merely scoring moderately.
- Match the reader’s phrasing, not just the topic. If a paragraph covers the right idea but scores poorly, rewrite it using the words and framing the question itself uses, rather than more formal or internal terminology.
- Fix dangling references before touching anything else. A paragraph opening with “This approach…” will underperform regardless of how good its content is, because it isn’t self-contained once isolated. Name the subject directly.
- Split paragraphs carrying two ideas. A long paragraph often scores moderately against several questions instead of strongly against one — breaking it apart usually raises both scores.
- Re-run before moving on. Confirm a fix actually raised the specific cell you targeted in the heatmap, not just the overall score — a rewrite can shift the wrong cell if you’re not checking directly.
How Does LLM Optimization Fit Into the Rest of the AEO/GEO Workflow?
Retrieval and topical coverage are different problems, and treating them as one check produces a false sense of completeness. Run the Entity & Knowledge Graph Gap Mapper first to confirm the content addresses the concepts a knowledgeable source would be expected to cover. Then run the Real Retrieval Simulator to confirm the paragraphs you’ve written would actually surface for realistic reader questions. A rewrite that closes an entity gap can still leave a retrieval gap open, and vice versa, so re-running both checks after a substantial content update is worth the few minutes it takes.
The coverage side of that split is covered in Entity-First Content for GEO and AEO, and the free Entity Gap Mapper checks it for a specific page.
Neither check assesses writing quality, factual accuracy, domain trust, or competing content — both are single, specific signals, not full audits. Treat them as prerequisites that make a page eligible to be cited, not guarantees that it will be.
Stay Ahead of AI Search.
Weekly AEO, GEO & AI SEO intelligence for marketers who want their content cited by AI. No fluff.
Frequently Asked Questions
The Bottom Line
Word-count and formatting rules for AI-friendly writing are useful defaults, but they’re proxies for retrievability, not measurements of it. The only way to know whether a specific paragraph would actually surface for a specific reader question is to test the real thing: embed the content, embed the question, and measure the distance between them.
Run your content through the free Real Retrieval Simulator after you’ve confirmed topical entity coverage is solid, close the reddest gaps in the heatmap first, and re-run both checks after any substantial rewrite. Neither check is optional if the goal is content that AI systems can actually find and cite, not just content that looks correctly formatted.
Written by
AEO Insider Editorial Team
We help modern marketers and operators get their content cited by AI, discovered in search, and wired into scalable growth systems. Our collective focus is entirely on the cutting edge of AEO, GEO, and AI-native SEO.
ABOUT AEO Insider →
One Comment